Homework 2 - Tic'd Off
You certainly won't be tic'd after finishing this assignment (the professor said optimistically)!
The fun part: we get to play more games (or more accurately, make something that will play the games for us -- just like Twitch, and that's been pretty popular)!
What are we playing, you might ask?
Tic-Tac-Total
The game of Tic-Tac-Total (by yours truly, though kinda stolen from someone else's idea, but only a little -- it will fly in court) is played just like Tic-Tac-Toe, but instead of actions placing "Xs" and "Os", the players place numbers in an attempt to sum to 13!
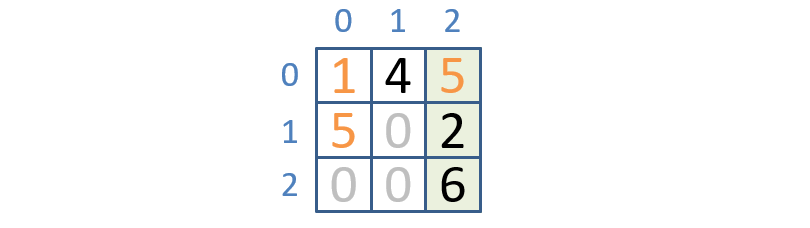
The rules:
2 players alternate turns placing a number in one of the available board tiles.
1 Player has the "odds": \(\{1, 3, 5\}\)
1 Player has the "evens": \(\{2, 4, 6\}\)
The board defaults to a 3 x 3 grid (but can be scaled arbitrarily upwards) and starts out with 0's in every cell; since this will be implemented as a 2D array of ints, we'll index rows starting at the top by 0, and columns starting at the left by 0.
The first player to form a sum of 13 in any of the traditional Tic-Tac-Toe directions (i.e., in any column, row, or corner-to-corner-diagonal of tiles) is the winner!
It is possible to tie in the event that all tiles are filled without any direction summing to 13.
In the board-state above (obviously two noobs not playing optimally), whichever player made the final placement of a number in the column on the right will be the winner.
Warning: this game is not particularly well balanced, but hey, the OG Tic-Tac-Toe ain't perfect either.
Example Playthrough
Here is an example execution of T3 with the agent (the opponent, playing Evens) against a human (going first, playing odds... the poor soul):
================================
=              T3              =
================================
[0, 0, 0]
[0, 0, 0]
[0, 0, 0]

Enter three space-separated numbers in format: COL ROW NUMBER
[Player's Turn: Move Options [1, 3, 5]] > 1 1 5
[0, 0, 0]
[0, 5, 0]
[0, 0, 0]

[Opponent's Turn] > (0,0) = 2
[2, 0, 0]
[0, 5, 0]
[0, 0, 0]

Enter three space-separated numbers in format: COL ROW NUMBER
[Player's Turn: Move Options [1, 3, 5]] > 1 0 1
[2, 1, 0]
[0, 5, 0]
[0, 0, 0]

[Opponent's Turn] > (2,2) = 6
[2, 1, 0]
[0, 5, 0]
[0, 0, 6]

[L] You Lose!
Your Task
Implement α-β Pruning Minimax to construct an agent that plays the game of Tic-Tac-Total (or T3 for short)!
This agent will play optimally against an opponent (human or otherwise) on games of T3.
In particular, you will gain practice with the following topics:
Game Trees as Recursion: in the past, we've constructed search trees / graphs for classical search problems, but for canonical games, we do not need to preserve nodes in memory since we care only about the next, optimal move.
Pruning: in Minimax search, we'll be able to stop exploring certain subtrees when we know that we've already found a better solution elsewhere, as by the tenets of the α-β pruning algorithm. You must implement this in your agent's approach as well!
Combinatoric Generation: in the past, I've given you the transitions for your search problems -- time for you to get some practice generating them as well!
In this section, we will state our assumptions about the problem, and then detail what you will need to accomplish your goal in the following Specifications.
Tie-Breaking
At times during the course of the game, several actions / moves on the board may look equally appealing to our agent. We'll have specific rules for breaking those ties and returning a single "correct" answer, which has practical implications: (1) it's easier to debug (and grade) and (2) we'll have rules to prevent our agents from "playing with their food" (delaying the game when they've already guaranteed a win = BM [bad manners]]).
The tiebreaking priority of T3 is thus specified as:
Highest Utility: remember: our agent is always the max player at the game tree's root. A move that maximizes utility will always take priority.
Earliest Termination: in the event that two actions have the same utility (e.g., both lead to wins), we'll break ties in order of the number of moves into the future that would be required to achieve that terminal (fewer moves = higher priority).
For example, if a move wins immediately, we'll prioritize that over a move that wins in 2 turns. Similarly, we'd prioritize a move that wins in 2 turns vs. 4.
We'll only consider this tiebreaking for the depths of moves / subtrees that are NOT pruned by the alpha-beta-pruning algorithm, so you won't have to worry about expending any extra computation.
Implementing this tiebreaking priority *will* require you to track the depth with which terminals are found in the recursive exploration of the conceptual game tree. It is left to you to decide where this feature will go in the pseudocode given in the spec below.
Earliest Action: if there are ties in BOTH utility and terminal depth, we'll break ties in order of their
T3Actionordering. This ranking is already given in theT3Action's__lt__override, which prioritizes earlier (1) column, then (2) row, then (3) move number.For example, if we denote our
T3Actionas(COL, ROW, MOVE), then the odd's player putting a 3 in col 1 and row 2 would be:(1, 2, 3)By the tiebreaking order, we'd prioritize
(0, 2, 3)over(1, 1, 1)because column 0 breaks the tie over column 1. Similarly, we'd prioritize(2, 2, 1)over(2, 2, 3)because the column and row are the same, but the move number is therefore smaller.
This is an important set of rules that will influence how you craft your T3State, T3Player -- reflect back to this ordering during the rest
of the spec, the tiebreaking order WILL be graded!
Solution Skeleton
Start with the solution skeleton in-hand! In the following project, I've given you the outline for the T3 game's supporting components The rest is up to you to implement the alpha-beta pruning minimax functionality to solve the given problem!
In the provided solution skeleton, I have given you an outline for how to accomplish A* search through the following components:
t3_game.py, an interactive console version of T3 in which a human player faces off against the AI that you design! Technically, you never need to run this if you don't want, but it's kinda fun to be crushed by an agent of your own making. This can also be useful for empirical testing and seeing the decisions your agent makes at each step of a game in sequence.t3_player.py, containing the logic for your AI agent! Here's where you'll be implementing the selection mechanics of your minimax and alpha-beta pruning algorithms.t3_action.py, a simple class that allows you to specify actions to be made on the T3 board state, specifying a column, row, and number to place.t3_state.py, all logic concerning the T3 board state, including the ability to get the transitions (which you must complete!) and available actions, and determine if the turn is for the odd / even player.t3_tests.py, some basic unit tests to validate your agent's behavior -- you should add to these to increase your confidence in your approach! See the testing and grading section below for more suggestions.mypy.ini, pytest.iniconfiguration files formypy, pytestrespectively. Do not change these!.gitignorea set of patterns for git to avoid committing. You may modify this file if your commit attempts to add any project files to the repo (e.g., VSCode.projectfiles orpycachefolders, which should not be submitted).
Specifications
|
GenAI use for the entirety of this assignment is BANNED for code production as it will shortcut your learning and generalizable skills (besides, there's not much code to write) though is always OK for understanding error messages, interpreting skeleton code, etc. as outlined in the syllabus. |
Review Codebase
What better way to get acquainted with the code... than by reading some awesome documentation?!
All you need to examine at the start are the methods and docstrings given in two classes: T3Action, T3State
  @dataclass
  class T3Action:
      """
      T3Actions are agent-specified manipulations on the game
      board such that they indicate which column, row, (both 0
      indexed), and number / move they would like to make.
      T3Actions implement Comparable and are ordered in ascending
      column, row, then move number.
      """

      _col: int
      _row: int
      _move: int

      def col(self) -> int:
          """
          Returns:
              int:
                  The column in which this action is placed
          """
          return self._col

      def row(self) -> int:
          """
          Returns:
              int:
                  The row in which this action is placed
          """
          return self._row

      def move(self) -> int:
          """
          Returns:
              int:
                  The number that is being placed on the board at this
                  action's location; will be different for the odds vs.
                  evens player
          """
          return self._move

      # Other methods omitted -- you should review these in t3_action.py,
      # as there are some implementation hints that may be useful later!
      # [Hint: pay attention to the __lt__ override]
  @dataclass
  class T3State:
      """
      Representation of the T3 grid board-state, which player's turn (odds / evens),
      and ability to obtain the actions and transitions possible (among other state
      utility methods).
      """

      # The maximum numerical move available to either player, though odds will get
      # all odds from 1 to MAX_MOVE (inclusive), and evens all even numbers
      MAX_MOVE = 6
      # The sum along any row, column, or diagonal that constitutes a win condition
      WIN_TARGET = 13
      # The default size of the game board, though can be arbitrarily larger
      DEFAULT_SIZE = 3

      def __init__(self, odd_turn: bool, state: Optional[list[list[int]]]):
          """
          Constructs a new T3 Board State from either the one provided,
          or the default, which will be a 3x3 empty grid. Which players turn
          is also specified.

          Parameters:
              odd_turn (bool):
                  Whether or not this is the odd player's turn (and if False,
                  therefore, it is the even player's)
              state (Optional[list[list[int]]]):
                  The board state, which must be a square N x N grid
          """

      def is_valid_action(self, act: "T3Action") -> bool:
          """
          Determines if the provided action is legal within this state, as decided by
          whether or not the col and row are in range of the board, that spot is not
          occupied, and whether the move number is within the set of allowable player
          actions on the given turn.

          Parameters:
              act (T3Action):
                  The action being judged for legality

          Returns:
              Whether or not the given act is legal in this board state
          """

      def get_next_state(self, act: Optional["T3Action"]) -> "T3State":
          """
          Returns the next state representing the transition from the current state (self)
          having taken the given action. E.g., if the player is at location (1,1) and
          moves Right (assuming there's no wall blocking them), then the returned state is
          that which has them in the position (2,1).

          Parameters:
              act (Optional[T3Action]):
                  The T3Action representing the move chosen by the agent in the current state.
                  [!] If None or an invalid action (e.g., runs into a wall), raises an error.

          Returns:
              T3State:
                  The next state that would be reached from taking the given act in the
                  current state.
          """

      def get_open_tiles(self) -> list[tuple[int, int]]:
          """
          Returns a list of (x,y) = (c,r) tuples indicating the open tiles into which
          players may place numbers in the current board state (i.e., returns the
          locations of all 0s on the board).

          Returns:
              list[tuple[int, int]]:
                  The list of (c,r) tuples of all 0s / open tiles on the board.
          """

      def get_moves(self) -> list[int]:
          """
          Returns the list of "move" options for any open tile available to the
          player whose turn it is in the current state.

          Examples:
              Odd player's turn in self:     [1, 3, 5]
              Even player's turn in self:    [2, 4, 6]

          Returns:
              list[int]:
                  The list of int moves available to the player in any open tile.
          """

      def is_win(self) -> bool:
          """
          Returns whether or not the current state is in a win condition, i.e.,
          at least one row, col, or diagonal has numbers that sum to WIN_TARGET.

          [!] Note: does not necessarily tell you *which* player won, as this state
          will represent the terminal *following* the player who made the winning move.

          Returns:
              bool:
                  Whether or not the current state is a terminal win state.
          """

      def is_tie(self) -> bool:
          """
          Returns whether or not the current state is a tie condition, i.e., the
          state is not a win for any player, and there are no more possible moves.

          Returns:
              bool:
                  Whether or not the state is a tie.
          """
Completing T3State
Now that you've reviewed the tools available to you (especially the methods in T3State), let's complete one important method that will
serve as the bridge into your T3Player implementation.
To start, let's motivate this with a simple example set of transitions.
  currentState =
  [2, 1, 2]
  [1, 1, 0]
  [2, 0, 6]

  odd's turn - moves: [1, 3, 5]
What would be the possible transitions from this state, noting that there are 2 locations available for the odds player to move and it's their turn (click for solution).
Each possible state with each of odd's actions in each of the available spots, e.g.
 {        moves in (1, 2)        }{        moves in (2, 1)        }
  [2, 1, 2]  [2, 1, 2]  [2, 1, 2]  [2, 1, 2]  [2, 1, 2]  [2, 1, 2]
  [1, 1, 0]  [1, 1, 0]  [1, 1, 0]  [1, 1, 1]  [1, 1, 3]  [1, 1, 5]
  [2, 1, 6]  [2, 3, 6]  [2, 5, 6]  [2, 0, 6]  [2, 0, 6]  [2, 0, 6]

      0          1          2          3          4          5
What do we notice about the transition in index 2 in the previous example?
It was a win for the odds player! They formed 13 along the bottom row. This makes for a case wherein there may be some alpha-beta-pruning that would prune the next states at indices 3+ -- so why invest the effort generating them?
Enter the use of Generators, which are Python functions that act like iterators (remember those
from Data Structures?) over some sequence of values that can be used in something like a for-each loop.
Here's an example for how to implement an Iterator for any arbitrary sequence!
The intuition: if we create a Generator function to make our Transitions in T3, then we'll never waste effort *making* next states that would have gotten pruned by the algorithm (compared to, e.g., returning a list of ALL of the transitions at once).
As such, complete the skeleton for the get_transitions Generator function stubbed below in t3_state.py:
  def get_transitions(self) -> Iterator[tuple["T3Action", "T3State"]]:
      """
      Returns a Generator of the transitions from this state, viz., tuples of
      T3Actions mapped to the next T3States they lead to from the current state.

      [!] Note: for convenience in the T3Player, should generate tuples in order
      of the T3Action tiebreaking order!

      Example:
          [6, 4, 1]
          [1, 1, 4]
          [4, 1, 0]

          If even's turn, there is 1 open tiles in which to move, with the
          following combos that would be generated (note each item is a tuple of
          the format (T3Action, T3State)):

          (T3Action(2, 2, 2),
           T3State(True, [
               [6, 4, 1],
               [1, 1, 4],
               [4, 1, 2]
           ]))
          (T3Action(2, 2, 4),
           T3State(True, [
               [6, 4, 1],
               [1, 1, 4],
               [4, 1, 4]
           ]))
          (T3Action(2, 2, 6),
           T3State(True, [
               [6, 4, 1],
               [1, 1, 4],
               [4, 1, 6]
           ]))

      Returns:
          Iterator[tuple["T3Action", "T3State"]]:
              A Generator of transition tuples of the format (T3Action, T3State)
      """
Aspects of T3State that will help in this regard:
Check out the T3State's
get_open_tiles, get_moves, get_next_statemethods -- they'll be useful here!In the next step (crafting the
T3Player), there are some rules for tiebreaking of returned actions that may influence how you design the *order* in which transitions are generated by this method. You might need to return to this method to make tweaks given that part of the spec, but for now, just get the transitions returned in some order. [Hint: using the helper methods mentioned above, the tiebreaking order will be easy to ensure]
Once you're confident that your generator is working as intended, you can run a couple of tests using: pytest -k transitions
Completing T3Player
You've got one important task here!
  def choose(state: "T3State") -> Optional["T3Action"]:
      """
      Main workhorse of the T3Player that makes the optimal decision from the max node
      state given by the parameter to play the game of Tic-Tac-Total.

      [!] Remember the tie-breaking criteria! Moves should be selected in order of:
      1. Best utility
      2. Smallest depth of terminal
      3. Earliest move (i.e., lowest col, then row, then move number)

      You can view tiebreaking as something of an if-ladder: i.e., only continue to
      evaluate the depth if two candidates have the same utility, only continue to
      evaluate the earliest move if two candidates have the same utility and depth.

      Parameters:
          state (T3State):
              The board state from which the agent is making a choice. The board
              state will be either the odds or evens player's turn, and the agent
              should use the T3State methods to simplify its logic to work in
              either case.

      Returns:
          Optional[T3Action]:
              If the given state is a terminal (i.e., a win or tie), returns None.
              Otherwise, returns the best T3Action the current player could take
              from the given state by the criteria stated above.
      """
      # [!] TODO! Implement alpha-beta-pruning minimax search!
Successful implementation of the choose method must employ α-β-pruning minimax WITH the tiebreaking criteria specified
in the overview!
[Repeated from Course Notes] Below, you'll find the algorithm for α-β Pruning. This pseudocode is 50% of what you need to implement for this assignment, the remaining 50% being how to:
Adapt the recursive method to not simply return the minimax score, but also, the optimal action leading to it.
How to interface with the given
T3Stateobjects to acquire all of the conceptual parts of the pseudocode below (e.g., how to get all "children" of a given "node")Choose utility scores and determine how / where they will be evaluated in your code.
How to implement the tiebreaking criteria, especially by taking the *depth* of a given terminal into consideration!
Reminder: below, references to "nodes" / "children" are simply conceptual -- although you'll be performing a depth-first search in the game tree conceptually, you should not construct any nodes nor actual game tree data structure (as this wastes unnecessary memory). All necessary components can be passed as parameters and then returned from recursive calls, as the following suggests.
That said, a small helper tuple class that collects answers like by having attributes of utilities and actions are acceptable.
  function alphabeta(node, α, β, turn)
    if node is a terminal node
      return the utility score of node
    if turn == MAX
      v = -∞
      for each child of node
        v = max(v, alphabeta(child, α, β, MIN))
        α = max(α, v)
        if β ≤ α
          break
      return v
    else
      v = ∞
      for each child of node
        v = min(v, alphabeta(child, α, β, MAX))
        β = min(β, v)
        if β ≤ α
          break
      return v
Note, Python 3+ has ∞ = float("inf"), which you'll be able to use for starting min / max values according to the pseudocode (note
how they are negated in some cases).
Ready to test your agent? I'd first suggest running through some test cases by-hand in the t3_game.py (simply run python t3_game.py to play),
and then also checking the sample unit tests in t3_tests.py by running pytest t3_tests.py. Remember, you can always target individual tests by using the command
pytest -k test_name where test_name can be any test name / pattern in the test files.
Hints
Some challenges, tips, and hints to consider:
Remember the tools from your review exercise in Classwork 1! Certain method overrides for implementing the tiebreaking might be useful.
Function getting out-of-hand complicated? Remember to use ample helper methods! This is ESPECIALLY true of implementing the recursive nature of alpha-beta-minimax.
Additionally, here's a good order of tasks to tackle:
Review your course notes and make sure you have a solid grasp on how Minimax Search is meant to operate, at least at a high-level. During this review, envision what fields and data structures may be relevant in your solution, paying special attention to what is recorded in each node, and how to translate that to a passed parameter instead.
Your Classwork 3 will be a useful companion to help you understand and implement this assignment.
Using the algorithm for α-β pruning given above, step through a small example by hand.
Once you've done the above, you should be ready to bring your T3Player to life!
Start early and ask questions! I'm here to help!
Testing & Grading
As mentioned, the full set of grading tests will test many edge cases compared to the samples given in t3_tests.py. Use these to judge the
quality of your solution, but make sure to add to these so that you're confident all bugs are squashed!
Important: as a test of your... testing, I'm expecting you to generate some edge cases that put the depth-tiebreaking order to work. Make sure your agent prioritizes moves that end the game sooner than later, all else equal! See tiebreaking rules in Overview section for more detail.
Your grade (out of a possible 100 points for homework exercises) will be based on the following:
Correctness: If good faith effort: -X points for each missed unit test (depending on a difficulty adjustment on the grading tests; typically, X=2 or 2.5). If incomplete or has errors: 0 / 100
Warning: your solutions must also be computationally efficient by the alpha-beta-pruning algorithm, and will be tested on large board states with some maximum compute time. Running
pytestwill ensure that your solution is meeting this timeout, but all unit tests that do not reach a solution in this time will be considered "failed."Though there will be time constraints on certain obvious moves, the state space to explore on even an empty board of this simple game is pretty darn big, so unit tests will take this into consideration and be generous on timing for large board states. Moreover, your agent is not expected to make the first move as odds on an empty board (this would explore most of the game tree without fancier symmetry optimizations, which you aren't expected to do).
Lastly, your agent should (without needing to modify its code) operate on partially-completed larger boards (like the 4x4 setting), and should be able to play as either evens or odds. Using the given helper methods to structure your solution will pass both of these cases with ease.
Style: Style grading will be assessed on homework, meaning choices like correct spacing, variable names, and simplified logic will be graded. Moreover, you'll receive a -5 point deduction if
mypy .yields ANY errors on your submission.
Submission
You will be submitting your assignments through PostCommit!
What
Complete the required methods in t3_state.py, t3_player.py that accomplishes the specification above, *in the exact project structure and package given* in the
skeleton above.
You must NOT modify any class' *public interface* (i.e., any public class or method signatures) in your submission!
How
To clone this assignment (if you need a refresher), consult the guide here:
To submit this assignment:
Simply push your final, submission copy to the PostCommit repository associated with your account.
Place your name at the top of *all* modified files (in appropriate docstring commenting fashion) AND in the accompanying
readmefile.