Assignment 2 - The Best Policy: Not Always Honesty
This assignment gives you some practice with Markov Decision Processes! Feel free to work in groups up to the group-size limit listed in the syllabus.
Attribution: UC Berkeley has made some courseware available for RL practice in this domain, which we will use for this assignment because it's really cool.
In particular, you will get to play around with:
Reward shaping, Discount Factors, Living Rewards, and other parameters that can tangibly shape the behavior of some fixed policy.
Value iteration and the solutions it finds for offline MDPs.
Q-learning for finding optimal policies for online MDPs.
Approximate Q-learning for improving the generalizability and learning rates of vanilla q-learners.
Solution Skeleton
Start with the solution skeleton in hand! The heavy lifting and spec below has been done by a team of dedicated educators over the course of decades, and the components for you to complete are highlighted in each section that follows.
Included in the above, you'll find:
| Files you'll edit: | |
valueIterationAgents.py |
A value iteration agent for solving known MDPs. |
qlearningAgents.py |
Q-learning agents for Gridworld, Crawler and Pacman. |
analysis.py |
A file to put your answers to questions given in the project. |
| Files you should read but NOT edit: | |
mdp.py |
Defines methods on general MDPs. |
learningAgents.py |
Defines the base classes ValueEstimationAgent and QLearningAgent, which your agents will extend. |
util.py |
Utilities, including util.Counter, which is particularly useful for Q-learners. |
gridworld.py |
The Gridworld implementation. |
featureExtractors.py |
Classes for extracting features on (state,action) pairs. Used for the approximate Q-learning agent (in qlearningAgents.py). |
| Files you can ignore: | |
environment.py |
Abstract class for general reinforcement learning environments. Used by gridworld.py. |
graphicsGridworldDisplay.py |
Gridworld graphical display. |
graphicsUtils.py |
Graphics utilities. |
textGridworldDisplay.py |
Plug-in for the Gridworld text interface. |
crawler.py |
The crawler code and test harness. You will run this but not edit it. |
graphicsCrawlerDisplay.py |
GUI for the crawler robot. |
autograder.py |
Project autograder |
testParser.py |
Parses autograder test and solution files |
testClasses.py |
General autograding test classes |
test_cases/ |
Directory containing the test cases for each question |
reinforcementTestClasses.py |
Project 3 specific autograding test classes |
MDPs
Mercifully, this project has been upgraded to Python 3.9, so no need to fret with older versions!
To get started, run Gridworld in manual control mode, which uses the arrow keys:
python gridworld.py -m
You will see the two-exit layout from class. The blue dot is the agent. Note that when you press up, the agent only actually moves north 80% of the time. Such is the life of a Gridworld agent!
You can control many aspects of the simulation. A full list of options is available by running:
python gridworld.py -h
The default agent moves randomly
python gridworld.py -g MazeGrid
You should see the random agent bounce around the grid until it happens upon an exit. Not the finest hour for an AI agent.
Note: The Gridworld MDP is such that you first must enter a pre-terminal state (the double boxes shown in the GUI) and then take the special ‘exit' action before the episode actually ends (in the true terminal state called TERMINAL_STATE, which is not shown in the GUI). If you run an episode manually, your total return may be less than you expected, due to the discount rate (-d to change; 0.9 by default).
Look at the console output that accompanies the graphical output (or use -t for all text). You will be told about each transition the agent experiences (to turn this off, use -q).
As in Pacman, positions are represented by (x,y) Cartesian coordinates and any arrays are indexed by [x][y], with 'north' being the direction of increasing y, etc. By default, most transitions will receive a reward of zero, though you can change this with the living reward option (-r).
Report
Throughout the assignment, you will be required to reflect and report on the various problems, which you should organize by problem number in a report to be located in
the /doc/ subdirectory named report.pdf
Unless otherwise stated, each question should be answered in 2+ sentences; do not sacrifice any necessary detail and make sure to use the appropriate vocabulary from the lectures where appropriate. Vague answers that restate the question or do not answer it fully will not receive full credit.
Specifications
|
GenAI use for the entirety of this assignment is BANNED for code production as it will shortcut your learning and generalizable skills (besides, there's not much code to write, the exercise is meant to teach you how to implement MDP solvers from first-principles) though is always OK for understanding error messages, interpreting skeleton code, etc. as outlined in the syllabus. |
Value Iteration
Recall the value iteration state update equation:
Write a value iteration agent in ValueIterationAgent, which has been partially specified for you in valueIterationAgents.py. Your value iteration agent is an offline planner, not a reinforcement learning agent, and so the relevant training option is the number of iterations of value iteration it should run (option -i) in its initial planning phase. ValueIterationAgent takes an MDP on construction and runs value iteration for the specified number of iterations before the constructor returns.
Value iteration computes \(k\)-step estimates of the optimal values, \(V_k\). In addition to runValueIteration, implement the following methods for ValueIterationAgent using \(V_k\).
computeActionFromValues(state)computes the best action according to the value function given byself.values.computeQValueFromValues(state, action)returns the Q-value of the (state, action) pair given by the value function given byself.values.
These quantities are all displayed in the GUI: values are numbers in squares, Q-values are numbers in square quarters, and policies are arrows out from each square.
Important: Use the "batch" version of value iteration where each vector \(V_k\) is computed from a fixed vector \(V_{k-1}\) (like in lecture), not the "online" version where one single weight vector is updated in place. This means that when a state's value is updated in iteration \(k\) based on the values of its successor states, the successor state values used in the value update computation should be those from iteration \(k-1\) (even if some of the successor states had already been updated in iteration \(k\)). The difference is discussed in Sutton & Barto in Chapter 4.1 on page 91.
Note: A policy synthesized from values of depth \(k\) (which reflect the next \(k\) rewards) will actually reflect the next \(k+1\) rewards (i.e. you return \(\pi_{k+1}\)). Similarly, the Q-values will also reflect one more reward than the values (i.e. you return \(Q_{k+1}\)).
You should return the synthesized policy \(\pi_{k+1}\).
Hint: You may optionally use the util.Counter class in util.py, which is a dictionary with a default value of zero. However, be careful with argMax: the actual argmax you want may be a key not in the counter!
Note: Make sure to handle the case when a state has no available actions in an MDP (think about what this means for future rewards).
To test your implementation, run the autograder:
python autograder.py -q q1
If the command above fails, citing issues with an import like the imp module, it's likely because you're using an incompatible version of Python. Use tools like miniconda or pyenv to run using Python 3.9.
The following command loads your ValueIterationAgent, which will compute a policy and execute it 10 times. Press a key to cycle through values, Q-values, and the simulation. You should find that the value of the start state (V(start), which you can read off of the GUI) and the empirical resulting average reward (printed after the 10 rounds of execution finish) are quite close.
python gridworld.py -a value -i 100 -k 10
Hint: On the default BookGrid, running value iteration for 5 iterations should give you this output:
python gridworld.py -a value -i 5
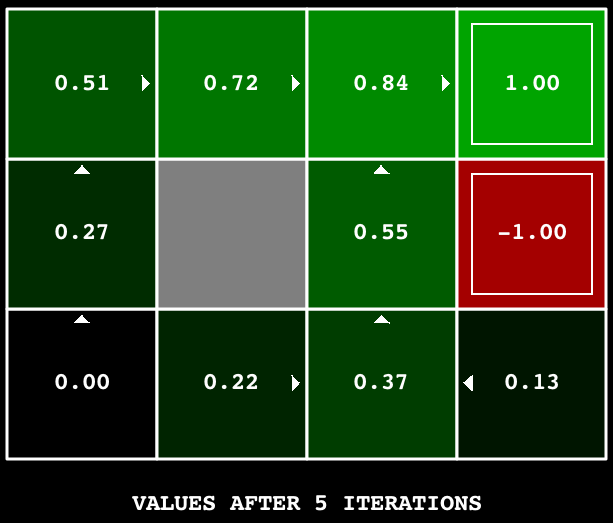
Grading: Your value iteration agent will be graded on a new grid. We will check your values, Q-values, and policies after fixed numbers of iterations and at convergence (e.g. after 100 iterations).
Report (to be completed once the grading tests above are passing):
Use the execution syntax from above python gridworld.py -a value -i [NUM_ITERATIONS] -k 10 --discount [DISCOUNT] --noise [NOISE] --livingReward [LIVING_REWARD] to answer the questions that follow:
Without changing the discount, noise, or livingReward (i.e., don't specify those parameters in the pattern above), screenshot the values and q-values of value iteration with
-i= 0, 1, 2.Explain why it took until
-i=1for the terminal rewards to appear.Explain why, for the
i=2case, the q-values \(Q(s,a)\) for the space directly left of the fiery pit (the -1 tile) are non-zero, but the value of this tile \(V_2(s)=0\). You may want to draw part of the expectimax tree as part of your answer.Run the simulation with parameters
python gridworld.py -a value -i 100 --livingReward 0.01 --discount 1and take a screenshot of the result for your report.Run the simulation with parameters
python gridworld.py -a value -i 100 --livingReward 0.01 --discount 0.9and take a screenshot of the result for your report.Explain why the policies are different between the simulations in items 4 and 5 above.
Policy Shaping
Consider the DiscountGrid layout, shown below. This grid has two terminal states with positive payoff (in the middle row), a close exit with payoff +1 and a distant exit with payoff +10. The bottom row of the grid consists of terminal states with negative payoff (shown in red); each state in this "cliff" region has payoff -10. The starting state is the yellow square. We distinguish between two types of paths: (1) paths that "risk the cliff" and travel near the bottom row of the grid; these paths are shorter but risk earning a large negative payoff, and are represented by the red arrow in the figure below. (2) paths that "avoid the cliff" and travel along the top edge of the grid. These paths are longer but are less likely to incur huge negative payoffs. These paths are represented by the green arrow in the figure below.
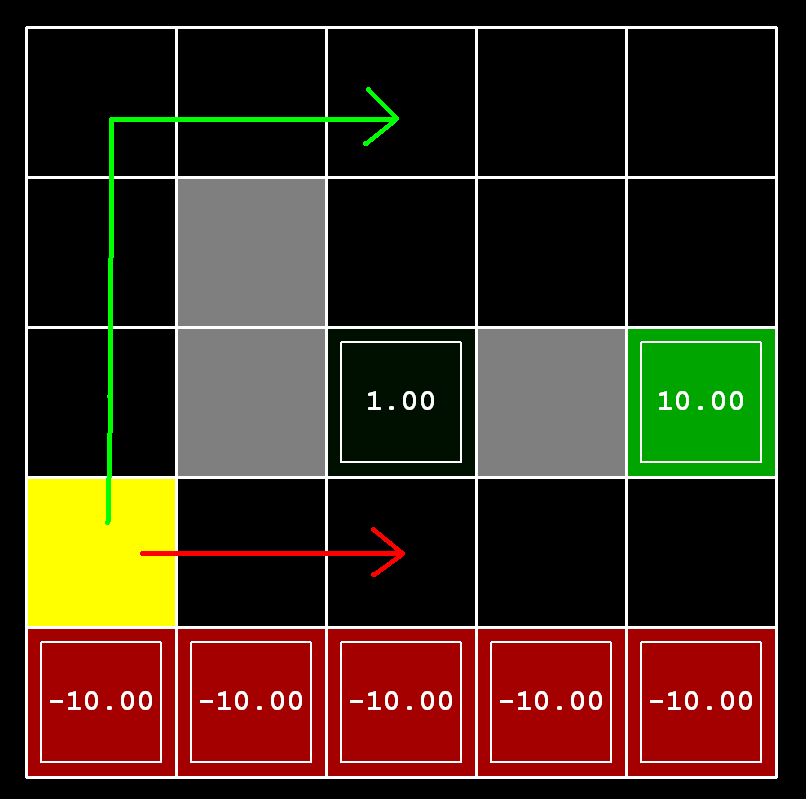
In this question, you will choose settings of the discount, noise, and living reward parameters for this MDP to produce optimal policies of several different types. Your setting of the parameter values for each part should have the property that, if your agent followed its optimal policy in the MDP, it would exhibit the given behavior. If a particular behavior is not achieved for any setting of the parameters, assert that the policy is impossible by returning the string 'NOT POSSIBLE'.
Here are the optimal policy types you should attempt to produce:
- Prefer the close exit (+1), risking the cliff (-10)
- Prefer the close exit (+1), but avoiding the cliff (-10)
- Prefer the distant exit (+10), risking the cliff (-10)
- Prefer the distant exit (+10), avoiding the cliff (-10)
- Avoid both exits and the cliff (so an episode should never terminate)
To see what behavior a set of numbers ends up in, run the following command to see a GUI:
python gridworld.py -g DiscountGrid -a value --discount [YOUR_DISCOUNT] --noise [YOUR_NOISE] --livingReward [YOUR_LIVING_REWARD] To check your answers, run the autograder:
python autograder.py -q q2
question2a() through question2e() should each return a 3-item tuple of (discount, noise, living reward) in analysis.py.
Note: For example, using a correct answer to 2(a), the arrow in (0,1) should point east, the arrow in (1,1) should also point east, and the arrow in (2,1) should point north.
Note: On some machines you may not see an arrow. In this case, press a button on the keyboard to switch to qValue display, and mentally calculate the policy by taking the arg max of the available qValues for each state.
Report (to be completed BEFORE the grading tests above are passing):
In a sentence each, define the purpose of each of the following and what effects each of the following have on the agent's policy:
Terminal Rewards
Living Rewards
Transition Noise
Discount Factor
If the
livingReward = -1, noise = 0.8, would it be possible to find a value of the discount factor such that the agent's policy (starting at the yellow square above) prefers ONLY the distant exit (+10)? If so, what value and why? If not, why?
Grading: We will check that the desired policy satisfying the described behavior is returned in each case specified in items 1-5.
Q-Learning
Note that your value iteration agent does not actually learn from experience. Rather, it ponders its MDP model to arrive at a complete policy before ever interacting with a real environment. When it does interact with the environment, it simply follows the precomputed policy (e.g. it becomes a reflex agent). This distinction may be subtle in a simulated environment like a Gridword, but it's very important in the real world, where the real MDP is not available.
You will now write a Q-learning agent, which does very little on construction, but instead learns by trial and error from interactions with the environment through its update(state, action, nextState, reward) method. A stub of a Q-learner is specified in QLearningAgent in qlearningAgents.py, and you can select it with the option '-a q'. For this question, you must implement the update, computeValueFromQValues, getQValue, and computeActionFromQValues methods.
Note: For computeActionFromQValues, you should break ties randomly for better behavior. The random.choice() function will help. In a particular state, actions that your agent hasn't seen before still have a Q-value, specifically a Q-value of zero, and if all of the actions that your agent has seen before have a negative Q-value, an unseen action may be optimal.
Important: Make sure that in your computeValueFromQValues and computeActionFromQValues functions, you only access Q values by calling getQValue . This abstraction will be useful for question 6 when you override getQValue to use features of state-action pairs rather than state-action pairs directly.
With the Q-learning update in place, you can watch your Q-learner learn under manual control, using the keyboard:
python gridworld.py -a q -k 5 -m
Recall that -k will control the number of episodes your agent gets to learn. Watch how the agent learns about the state it was just in, not the one it moves to, and "leaves learning in its wake." Hint: to help with debugging, you can turn off noise by using the --noise 0.0 parameter (though this obviously makes Q-learning less interesting). If you manually steer Pacman north and then east along the optimal path for four episodes, you should see the following Q-values:
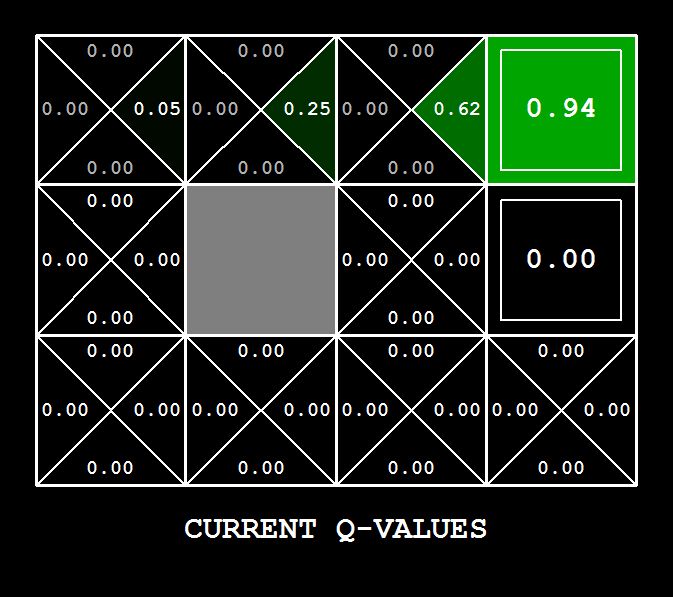
Grading: We will run your Q-learning agent and check that it learns the same Q-values and policy as our reference implementation when each is presented with the same set of examples. To grade your implementation, run the autograder:
python autograder.py -q q3
Report (to be completed once the grading tests above are passing):
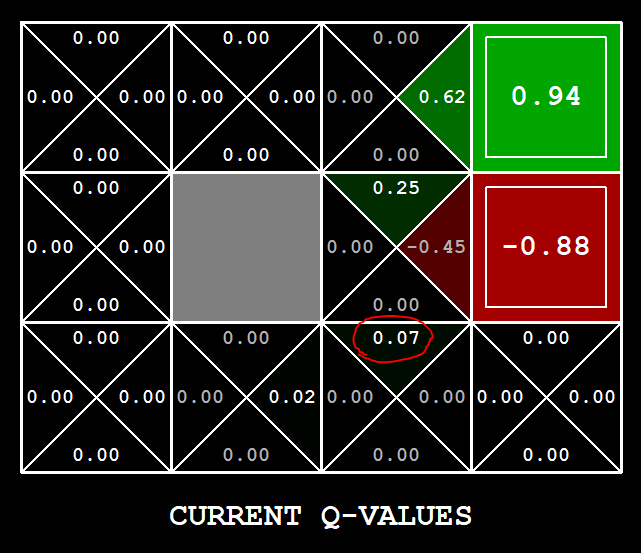
Consider the following Q-values of a Q-learning agent mid-learning process, who has only tread the bottom path to each of the terminals a handful of times. Explain why the circled value of 0.07 is positive, even though the next state it leads to (next to the pit) has experientially encountered a larger negative q-value (-0.45) than positive (0.25.)
Q-Learning + \(\epsilon-Greedy\)
Complete your Q-learning agent by implementing epsilon-greedy action selection in getAction, meaning it chooses random actions an epsilon fraction of the time, and follows its current best Q-values otherwise. Note that choosing a random action may result in choosing the best action - that is, you should not choose a random sub-optimal action, but rather any random legal action.
You can choose an element from a list uniformly at random by calling the random.choice function. You can simulate a binary variable with probability p of success by using util.flipCoin(p), which returns True with probability p and False with probability 1-p.
After implementing the getAction method, observe the following behavior of the agent in gridworld (with epsilon = 0.3).
python gridworld.py -a q -k 100
Your final Q-values should resemble those of your value iteration agent, especially along well-traveled paths. However, your average returns will be lower than the Q-values predict because of the random actions and the initial learning phase.
To test your implementation, run the autograder:
python autograder.py -q q4
With no additional code, you should now be able to run a Q-learning crawler robot:
python crawler.py
Report (to be completed once the grading tests above are passing):
-
With all transition noise turned off, observe the effects of two different values of epsilon (exploration rate) on how quickly the optimal policy is learned by running:
  python gridworld.py -a q -k 100 --noise 0.0 -e 0.1
  python gridworld.py -a q -k 100 --noise 0.0 -e 0.9
Comparing these simulations, answer the following questions:
Which learns the optimal policy more quickly and why?
Which learns more q-values and why?
Which could be described as "more reckless" in its exploration and why?
Using your answer to the above, when would you want to use a higher exploration rate and when would you want a lower?
Why also would this algorithm be reckless/unethical to use in real-world scenarios rather than in simulations first before deploying to real-world settings?
-
Ready for a modest amount of nightmare fuel? Time to check out... ThE CrAwLeR:
python crawler.pyIf this doesn't work, you've probably written some code too specific to the
GridWorldproblem and you should make it more general to all MDPs.This will invoke the crawling robot from class using your Q-learner. Play around with the various learning parameters to see how they affect the agent's policies and actions. Note that the step delay is a parameter of the simulation, whereas the learning rate and epsilon are parameters of your learning algorithm, and the discount factor is a property of the environment.
Note that this uses exactly the same q-learning code you wrote for the noisy gridworld but looks very different! Briefly describe the following pieces of the MDP that would reuse your Q-learning code for the crawler environment: (1) state, (2) actions, (3) rewards.
Let ole Crawley explore for a bit with a high value of epsilon. Around what trial does that sucker start scooting pretty reliably if you turn epsilon down low? Take a screenshot of Crawley reaching the right side of the panel for his photo finish.
Pacman Q-Learning
Note that if all previous parts have been done correctly, you do not need to write any code for this question. This is essentially an integration test.
Time to play some Pacman! Pacman will play games in two phases. In the first phase, training, Pacman will begin to learn about the values of positions and actions. Because it takes a very long time to learn accurate Q-values even for tiny grids, Pacman's training games run in quiet mode by default, with no GUI (or console) display. Once Pacman's training is complete, he will enter testing mode. When testing, Pacman's self.epsilon and self.alpha will be set to 0.0, effectively stopping Q-learning and disabling exploration, in order to allow Pacman to exploit his learned policy. Test games are shown in the GUI by default. Without any code changes you should be able to run Q-learning Pacman for very tiny grids as follows:
python pacman.py -p PacmanQAgent -x 2000 -n 2010 -l smallGrid
Note that PacmanQAgent is already defined for you in terms of the QLearningAgent you've already written. PacmanQAgent is only different in that it has default learning parameters that are more effective for the Pacman problem (epsilon=0.05, alpha=0.2, gamma=0.8). You will receive full credit for this question if the command above works without exceptions and your agent wins at least 80% of the time. The autograder will run 100 test games after the 2000 training games.
Hint: If your QLearningAgent works for gridworld.py and crawler.py but does not seem to be learning a good policy for Pacman on smallGrid, it may be because your getAction and/or computeActionFromQValues methods do not in some cases properly consider unseen actions. In particular, because unseen actions have by definition a Q-value of zero, if all of the actions that have been seen have negative Q-values, an unseen action may be optimal. Beware of the argmax function from util.Counter!
Note: To grade your answer, run:
python autograder.py -q q5
Note: If you want to experiment with learning parameters, you can use the option -a, for example -a epsilon=0.1,alpha=0.3,gamma=0.7. These values will then be accessible as self.epsilon, self.gamma and self.alpha inside the agent.
Note: While a total of 2010 games will be played, the first 2000 games will not be displayed because of the option -x 2000, which designates the first 2000 games for training (no output). Thus, you will only see Pacman play the last 10 of these games. The number of training games is also passed to your agent as the option numTraining.
During training, you will see output every 100 games with statistics about how Pacman is faring. Epsilon is positive during training, so Pacman will play poorly even after having learned a good policy: this is because he occasionally makes a random exploratory move into a ghost. As a benchmark, it should take between 1000 and 1400 games before Pacman's rewards for a 100 episode segment becomes positive, reflecting that he's started winning more than losing. By the end of training, it should remain positive and be fairly high (between 100 and 350).
Make sure you understand what is happening here: the MDP state is the exact board configuration facing Pacman, with the now complex transitions describing an entire ply of change to that state. The intermediate game configurations in which Pacman has moved but the ghosts have not replied are not MDP states, but are bundled in to the transitions.
Once Pacman is done training, he should win very reliably in test games (at least 90% of the time), since now he is exploiting his learned policy.
Grading: To grade your answer, run the autograder:
python autograder.py -q q5
Report (to be completed once the grading tests above are passing):
Observe a few early training rounds of Pacman learning on the smallGrid environment:
python pacman.py -p PacmanQAgent -n 10 -l smallGrid -a numTraining=10
Explain why Pacman doesn't appear to move a lot, either away from the ghosts or towards the pellets, in these early training samples.
Let's kick things up a notch and pivot to the mediumGrid environment, in which we'll let Pacman learn via the same number trials as the smallGrid:
python pacman.py -p PacmanQAgent -x 2000 -n 2010 -l mediumGrid
Explain Pacman's behavior here and why he was not able to win in this new environment with 2000 training rounds.
Incrementing your training by 1000 rounds each time (i.e., trying 3000 then 4000 then 5000 etc.) determine how much training is needed with exact Q-learning before Pacman consistently wins on the mediumGrid. (hint: you'll need to change the -x and -n parameters above and MAY want to do a binary search to find the answer -- it's quite large!)
Approximate Q-Learning
Implement an approximate Q-learning agent that learns weights for features of states, where many states might share the same features. Write your implementation in ApproximateQAgent class in qlearningAgents.py, which is a subclass of PacmanQAgent.
Note: Approximate Q-learning assumes the existence of a feature function \(f(s,a)\) over state and action pairs, which yields a vector \([f_1(s,a), \ …, \ f_i(s,a), \ …, \ f_n(s,a)]\) of feature values. We provide feature functions for you in featureExtractors.py. Feature vectors are util.Counter (like a dictionary) objects containing the non-zero pairs of features and values; all omitted features have value zero.
The approximate Q-function takes the following form:
where each weight \(w_i\) is associated with a particular feature \(f_i(s,a)\). In your code, you should implement the weight vector as a dictionary mapping features (which the feature extractors will return) to weight values. You will update your weight vectors similarly to how you updated Q-values:
Note that the \(\text{difference}\) term is the same as in normal Q-learning, and \(r\) is the experienced reward.
By default, ApproximateQAgent uses the IdentityExtractor, which assigns a single feature to every (state,action) pair. With this feature extractor, your approximate Q-learning agent should work identically to PacmanQAgent. You can test this with the following command:
python pacman.py -p ApproximateQAgent -x 2000 -n 2010 -l smallGrid
Important:ApproximateQAgent is a subclass of QLearningAgent, and it therefore shares several methods like getAction. Make sure that your methods in QLearningAgent call getQValue instead of accessing Q-values directly, so that when you override getQValue in your approximate agent, the new approximate q-values are used to compute actions.
Once you're confident that your approximate learner works correctly with the identity features, run your approximate Q-learning agent with our custom feature extractor, which can learn to win with ease:
python pacman.py -p ApproximateQAgent -a extractor=SimpleExtractor -x 50 -n 60 -l mediumGrid
Even much larger layouts should be no problem for your ApproximateQAgent (warning: this may take a few minutes to train):
python pacman.py -p ApproximateQAgent -a extractor=SimpleExtractor -x 50 -n 60 -l mediumClassic
If you have no errors, your approximate Q-learning agent should win almost every time with these simple features, even with only 50 training games.
Grading: We will run your approximate Q-learning agent and check that it learns the same Q-values and feature weights as our reference implementation when each is presented with the same set of examples. To grade your implementation, run the autograder:
python autograder.py -q q6
Report (to be completed once the grading tests above are passing):
-
Explain how your agent is able to learn the optimal policy so much more quickly on the mediumGrid compared to the exact Q learner from the previous problem:
python pacman.py -p ApproximateQAgent -a extractor=SimpleExtractor -x 50 -n 60 -l mediumGrid
-
Note the implementation of the
IdentityExtractorthat returns the current state-action pair as its own feature with value of 1 (and therefore, all other state-action pairs would be features with value of 0 in the feature vector, by default). Explain how this makes an Approximate Q Learner with these features precisely the same as an Exact Q Learner:class IdentityExtractor(FeatureExtractor): def getFeatures(self, state, action): feats = util.Counter() feats[(state,action)] = 1.0 return feats -
Note also how the
SimpleExtractorfeature extractor is implemented and answer the questions that follow:class SimpleExtractor(FeatureExtractor): """ Returns simple features for a basic reflex Pacman: - whether food will be eaten - how far away the next food is - whether a ghost collision is imminent - whether a ghost is one step away """ def getFeatures(self, state, action): # extract the grid of food and wall locations and get the ghost locations food = state.getFood() walls = state.getWalls() ghosts = state.getGhostPositions() features = util.Counter() features["bias"] = 1.0 # compute the location of pacman after he takes the action x, y = state.getPacmanPosition() dx, dy = Actions.directionToVector(action) next_x, next_y = int(x + dx), int(y + dy) # count the number of ghosts 1-step away features["#-of-ghosts-1-step-away"] = sum((next_x, next_y) in \ Actions.getLegalNeighbors(g, walls) for g in ghosts) # if there is no danger of ghosts then add the food feature if not features["#-of-ghosts-1-step-away"] and food[next_x][next_y]: features["eats-food"] = 1.0 dist = closestFood((next_x, next_y), food, walls) if dist is not None: # make the distance a number less than one otherwise the update # will diverge wildly features["closest-food"] = float(dist) / (walls.width * walls.height) features.divideAll(10.0) return featuresNote the conditional addition of the food feature starting with the comment
# if there is no danger of ghosts then add the food feature. Knowing that getting eaten by ghosts carries a large penalty, what would happen if this condition were removed, i.e., that the food feature is added whether or not ghosts are nearby?Note also the scaling of distance-based features to be less than one in the logic starting with the comment
# make the distance a number less than one otherwise the update will diverge wildly. Ask ChatGPT to explain why it's preferable to keep feature values between [0, 1] in approximate Q learning and interpret its answer.
Congratulations! You have a learning Pacman agent!
Submission
You will be submitting your assignments through GitHub Classroom!
What
Complete all requested sections of each script specified above, ensuring that you pass the basic grading criteria in each for full credit. Moreover, make sure that you complete every requested report section
in your /doc/report.pdf
How
To clone this assignment (if you need a refresher), consult the guide here:
To submit this assignment:
Simply push your final, submission copy to the GitHub Classroom repository associated with your account.
Place your name at the top of *all* submitted files AND in the accompanying
readmefile.